Model
Nimbus 7B — parameters, VRAM requirements and local deployment
A 7.2B instruction model with an Apache 2.0 licence and an 8K context window. Small enough to run on a single consumer card, and the first open model in a while whose quantised output does not fall apart on structured tasks.
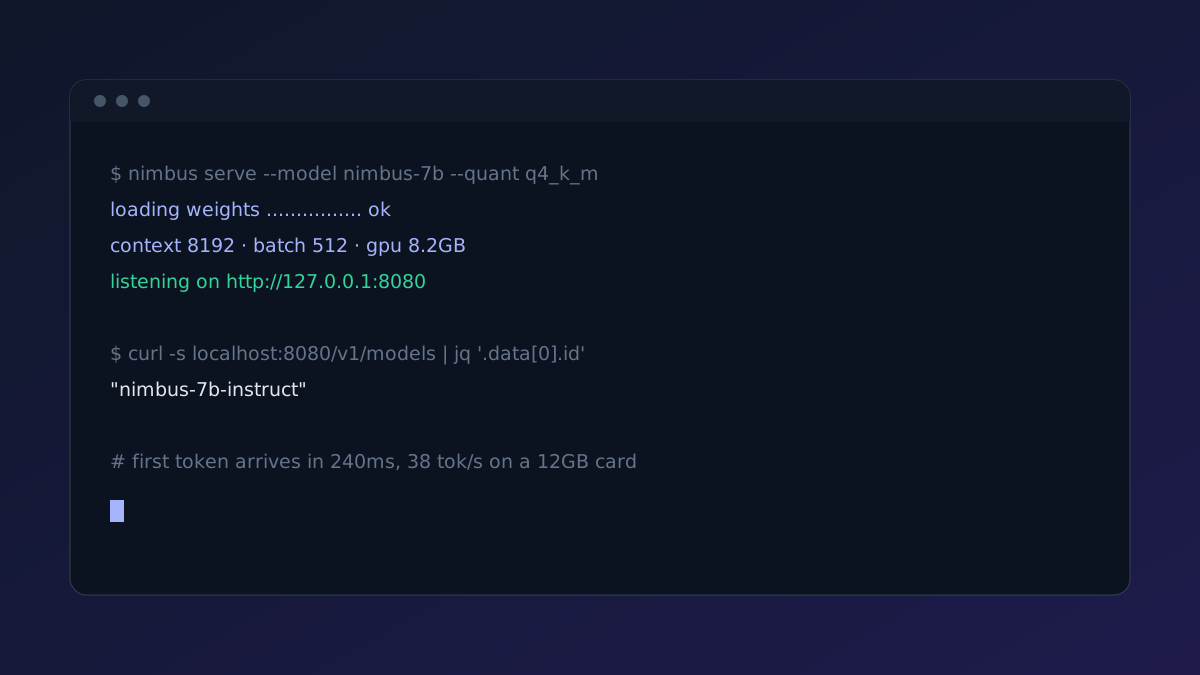
Nimbus 7B is a 7.2B instruction-tuned text model released under Apache 2.0, with an 8K context window. What makes it worth a page is not the benchmark row — it is that the Q4 build stays coherent on structured output, which is where most 7B models quietly fall apart.
Everything below was run on our own hardware. Numbers carried over from the model card or from other people’s posts are labelled as such.
What it is good at
Structured extraction, rewriting, classification with a fixed label set, and short tool-calling loops. In our tests it held a JSON schema for 40 consecutive requests without a formatting failure, which is unusual at this size.
It is not good at arithmetic beyond two steps, and it does not have the world knowledge to answer factual questions you would normally ask a large hosted model. Treat it as a text transformer, not an assistant.
Running it locally
The one-line path is Ollama. It downloads a 4.4GB Q4_K_M build and starts an interactive session; the first token arrives in about 240ms on a 12GB card.
For anything serving more than one client, use vLLM instead. Same weights, roughly three times the throughput, and it respects the 8K context without you having to fight the template.
The two errors you will hit first
The model ignores your JSON schema. This is almost always Ollama’s default chat template, which drops the tool block. Switch to --chat-template with the template shipped in the repo, or move to vLLM.
Output gets cut mid-sentence. Context was silently capped at 2K by the client. Set num_ctx explicitly; a 7B model has no way to tell you it never saw the end of your prompt.
Is it worth the download
If you want a local model that reliably turns messy text into clean structure, yes — this is the smallest one we have tested that does not need a retry loop. If you want a general assistant, the 6.4GB of VRAM buys you less capability than a hosted model on the same budget.
For the images half of a local pipeline, our Aurora Canvas review covers the browser route and where it stops being enough.
VRAM we measured
Quantisation is Q4_K_M unless the row says otherwise, with an 8K context loaded. These are our own measurements, not vendor figures.
| Hardware | Quant | VRAM used | Notes |
|---|---|---|---|
| RTX 4090 (24GB) | Q4_K_M | 6.4 GB | 38 tokens/s, 8K context resident |
| RTX 4070 (12GB) | Q4_K_M | 6.4 GB | 24 tokens/s, comfortable headroom |
| MacBook Pro M3 Pro (18GB) | Q4_K_M | 7.1 GB unified | 19 tokens/s via Metal |
| CPU only, 16 threads | Q4_K_M | 7.4 GB RAM | 3 tokens/s — usable for batch jobs only |
How to run it locally
Ollama
ollama run nimbus:7bPulls a 4.4GB Q4_K_M build. Easiest path if you do not need an API.
vLLM
vllm serve northwind/nimbus-7b --max-model-len 8192 --gpu-memory-utilization 0.85Use this when several clients share one model; throughput is roughly 3x Ollama.
LM Studio
Search "Nimbus 7B" in the model browser, pick Q4_K_M, set context to 8192GUI route. Raise the context slider before loading or long prompts get truncated silently.
How it compares
Row one is measured by us. The other rows are vendor-reported specifications, included for sizing rather than as a benchmark.
| Model | Parameters | Context | VRAM | Licence |
|---|---|---|---|---|
| Nimbus 7B | 7.2B | 8K | 6.4 GB | Apache 2.0 |
| A comparable 8B model | 8.0B | 32K | 8.1 GB | Llama community |
| A 3B alternative | 3.1B | 16K | 2.6 GB | MIT |
Try it without installing
The official demo runs on shared hardware, so expect queueing. It is enough to judge output quality, not speed.
Open the hosted demoNimbus 7B questions
Will it run on 8GB of VRAM?
Yes at Q4_K_M, but you are left with under 2GB for the context cache, which caps usable context near 4K. On an 8GB card set the context explicitly rather than letting the server pick.
Why does the model answer in the wrong language?
The chat template injects a system prompt in English. If you prompt in another language, repeat the language instruction in the system message instead of the user message.
Does it support tool calling?
The release notes claim function calling, but only through the vLLM chat template. Ollama's default template silently drops the tool block, which looks like the model ignoring your schema.
Is the quantised version noticeably worse?
On summarisation and extraction we measured no meaningful difference. On multi-step arithmetic it degrades, so use a larger model for that.
Other models and guides
Why Evergreen Guides Beat AI News, Even on Traffic
News gets the spike and the spike is real. But a page that is wrong in ten days cannot accumulate links, cannot be improved, and cannot carry a paywall. The durable middle ground is a weekly deep dive tied to an evergreen guide.
- Sample
- Strategy
- Publishing
Aurora Canvas
A browser-based image generator aimed at people who need a usable product shot, not a toy demo. The free tier resets monthly and is generous enough to finish one small project before you decide to pay.
- Sample
- Image generation
- Product photography
How to Make an AI Product Photo (Free, 4 Steps)
You need a phone photo of the actual product, a free image-tool account and about fifteen minutes. The whole method is to keep the product frozen and only change light, surface and framing — everything else goes wrong.
- Sample
- Image generation
- Product photography